


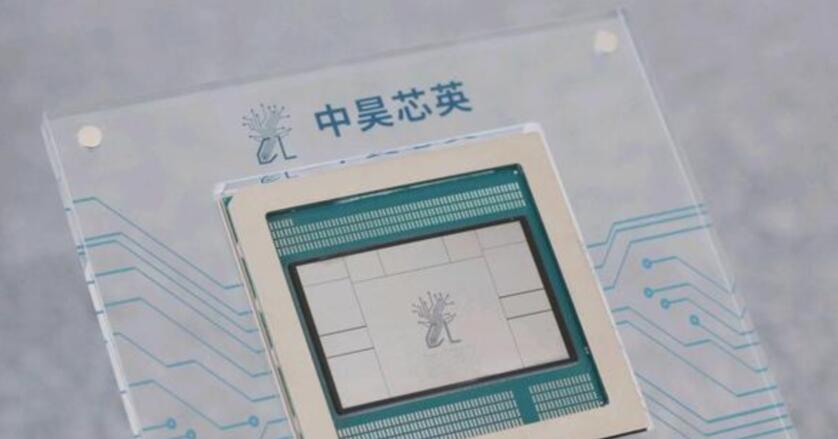
Cixin Silicon has unveiled its next-generation fully homegrown TPU chip, Xuyu®, alongside the Taize® 2.0 AI compute platform. The new chip succeeds the industry's first mass-produced domestic TPU (Shana® , 2023) with comprehensive upgrades in architecture, compute density, on-chip memory, interconnect, and power efficiency.

Xuyu® Core Specs:
-
896 TFLOPS mixed-precision floating-point – 3× Shana®
-
1,792 TOPS 8-bit inference – built for high-concurrency token推理
-
600W TDP – half the power of equivalent GPU solutions
-
Upgraded memory bandwidth and inter-chip transmission
-
Native support for ultra-long contexts, reducing redundant data movement
The chip delivers 2× effective compute efficiency over traditional GPUs on equivalent AI workloads, thanks to tensor-unit optimizations and data-reuse design – excelling in both training and batch generation.
Fully sovereign stack: IP cores, instruction sets, operator libraries, and system software are all self-developed – zero foreign core dependencies. It meets compliance requirements for government, finance, and power grid sectors.
Taize® 2.0 Platform:
-
Single node: dual CPUs + 8 Xuyu TPUs – 7.17 PetaFLOPS mixed-precision per node
-
Total node power consumption: 80% of equivalent GPU servers
-
Supports up to 2,048 Xuyu chips in a single super-node via low-latency proprietary interconnect
-
Handles trillion-parameter training, multi-agent coordination, and massive token concurrency
Includes integrated visual O&M with remote management, real-time monitoring, fault alerts, billing, access control, and a model marketplace. Software natively supports PyTorch, vLLM, SGLang, DeepSpeed, and Megatron-LM – already adapted to Qwen, DeepSeek, GLM, and dozens of LLMs.
Built for the Token Economy: As AI shifts to usage-based MaaS models, Xuyu optimizes token generation, context caching, and batch inference at the hardware level – cutting per-inference costs. It also supports private, on-premises OpenClaw-based agents, keeping all interaction data local – ideal for digital workers in finance, O&M, and analytics.
Cost advantage: Taize 2.0 delivers 60% of the build cost of comparable imported high-end gear, with low power draw cutting data center electricity and carbon footprints – aligning with green computing policies.
Deployment track record: Shana® already powers commercial deployments at China Unicom Shenzhen, China Mobile Tianjin, Taiji Computer, and multiple university research clusters. Cixin Silicon plans continued TPU iteration for larger models and multi-agent clusters, while deepening co-engineering with model providers and cloud vendors.
ICgoodFind :
896 TFLOPS at 600W with full-stack sovereignty – this is a serious contender. For enterprises under localization mandates, Xuyu offers a viable GPU alternative with better TCO. Watch for adoption in state-owned cloud and smart city tenders.







